
Machine Learning, Springer 2022 · 2022
Aliasing and adversarial robust generalization of CNNs
Why this publication matters
A network can become less reliable even while its training continues to improve. This study links that loss of robustness to artifacts introduced when internal images are reduced in size. Monitoring those artifacts offers a practical signal for stopping training before its benefits start to disappear.
Abstract
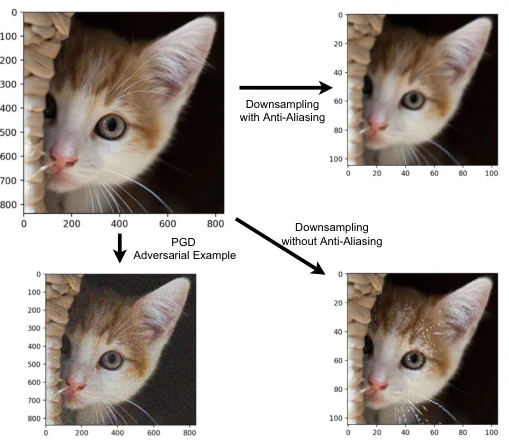
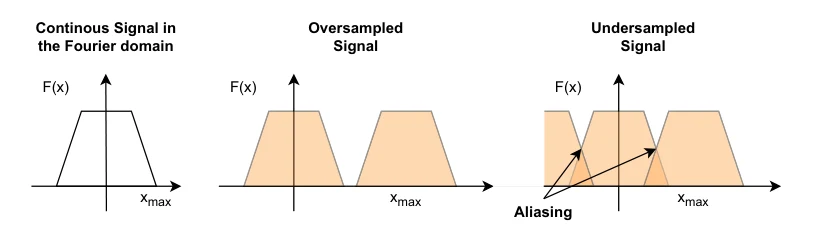
Many commonly well-performing convolutional neural network models have shown to be susceptible to input data perturbations, indicating a low model robustness. To reveal model weaknesses, adversarial attacks are specifically optimized to generate small, barely perceivable image perturbations that flip the model prediction. Robustness against attacks can be gained by using adversarial examples during training, which in most cases reduces the measurable model attackability. Unfortunately, this technique can lead to robust overfitting, which results in non-robust models. In this paper, we analyze adversarially trained, robust models in the context of a specific network operation, the downsampling layer, and provide evidence that robust models have learned to downsample more accurately and suffer significantly less from downsampling artifacts, aka. aliasing, than baseline models. In the case of robust overfitting, we observe a strong increase in aliasing and propose a novel early stopping approach based on the measurement of aliasing.
Figures
Cite this paper
@article{grabinski2022aliasingandadversarial14,
  title = {{Aliasing and adversarial robust generalization of CNNs}},
  author = {Julia Grabinski and Janis Keuper and Margret Keuper},
  journal = {Machine Learning},
  year = {2022},
  url = {https://link.springer.com/article/10.1007/s10994-022-06222-8},
  doi = {10.1007/s10994-022-06222-8}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.