
NeurIPS 22, proceedings of the thirty-sixth Conference on Neural Information Processing Systems · 2022
Robust Models are less Over-Confident
Why this publication matters
Reliable AI should avoid sounding certain when it is wrong. This study examines how training against deliberately difficult inputs also changes confidence on normal images. It shows that both the training method and the model's internal building blocks influence this useful, sometimes overlooked behavior.
Abstract
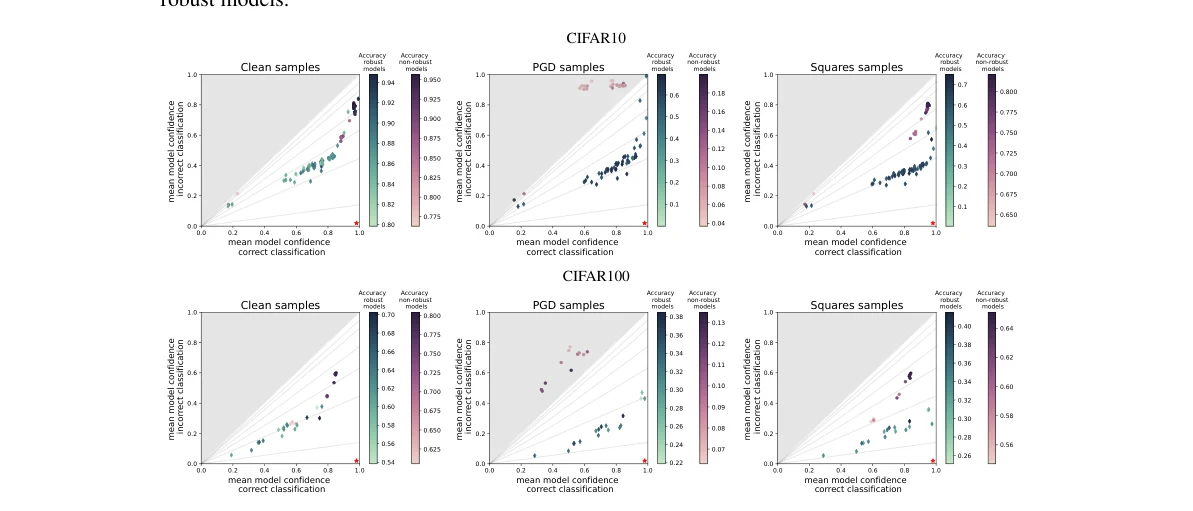
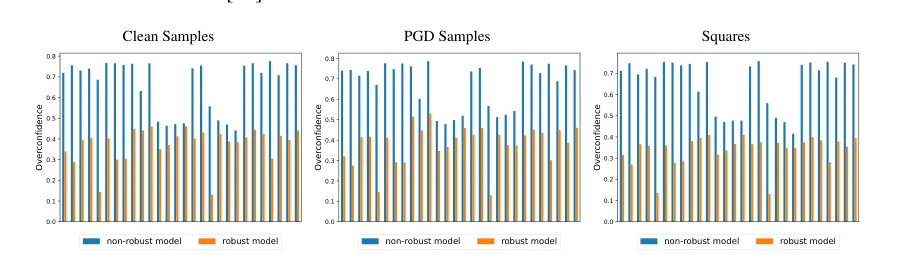
Despite the success of convolutional neural networks (CNNs) in many academic benchmarks for computer vision tasks, their application in the real-world is still facing fundamental challenges. One of these open problems is the inherent lack of robustness, unveiled by the striking effectiveness of adversarial attacks. Current attack methods are able to manipulate the network’s prediction by adding specific but small amounts of noise to the input. In turn, adversarial training (AT) aims to achieve robustness against such attacks and ideally a better model generalization ability by including adversarial samples in the trainingset. However, an in-depth analysis of the resulting robust models beyond adversarial robustness is still pending. In this paper, we empirically analyze a variety of adversarially trained models that achieve high robust accuracies when facing state-of-the-art attacks and we show that AT has an interesting side-effect: it leads to models that are significantly less overconfident with their decisions, even on clean data than non-robust models. Further, our analysis of robust models shows that not only AT but also the model’s building blocks (like activation functions and pooling) have a strong influence on the models’ prediction confidences. Data & Project website: https://github.com/GeJulia/robustness_confidences_evaluation
Figures
Cite this paper
@inproceedings{grabinski2022robustmodelsare22,
  title = {{Robust Models are less Over-Confident}},
  author = {Julia Grabinski and Paul Gavrikov and Janis Keuper and Margret Keuper},
  booktitle = {Advances in Neural Information Processing Systems},
  year = {2022},
  url = {https://arxiv.org/pdf/2210.05938}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.