
ACL 25 · 2025
Balancing Diversity and Risk in LLM Sampling - How to Select Your Method and Parameter for Open-Ended Text Generation
Why this publication matters
The settings used to sample an AI model's next word affect both variety and the risk of unreliable continuations. This work makes that trade-off easier to measure and compare. It offers practical guidance for choosing generation settings instead of relying solely on a familiar default.
Abstract
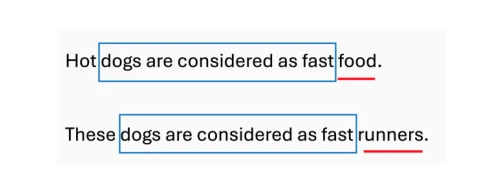
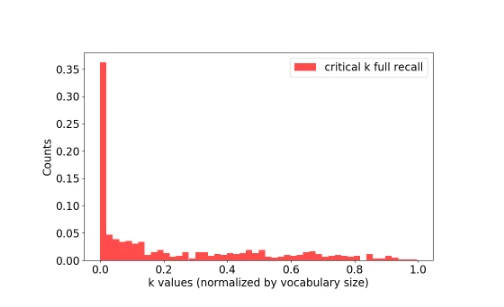
Sampling-based decoding strategies have been widely adopted for Large Language Models (LLMs) in numerous applications, targeting a balance between diversity and quality via temperature tuning and tail truncation. Considering the strong dependency of the candidate next tokens on different prefixes, recent studies propose to adaptively truncate the tail of LLMs’ predicted distribution. Although improved results have been reported with these methods on open-ended text generation tasks, the results are highly dependent on the curated parameters and the limited exemplar text. In this paper, we propose a systematic way to estimate the capacity of a truncation sampling method by considering the trade-off between diversity and risk at each decoding step, based on our collected prefix tree which preserves the context of a full sentence. Our work offers a comprehensive comparison of existing truncation sampling methods and serves as a practical user guideline for their parameter selection. Our code is available at github repository.
Figures
Cite this paper
@inproceedings{zhou2025balancingdiversityand68,
  title = {{Balancing Diversity and Risk in LLM Sampling - How to Select Your Method and Parameter for Open-Ended Text Generation}},
  author = {Yuxuan Zhou and Margret Keuper and Mario Fritz},
  booktitle = {Annual Meeting of the Association for Computational Linguistics},
  year = {2025},
  url = {https://openreview.net/forum?id=7bwwDHoDU4}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.