
Proceedings of the IEEE/CVF International Conference on Computer Vision Workshops (ICCVw 2025) · 2025
Missing Fine Details in Images - Last Seen in High Frequencies
Why this publication matters
Image generators can lose fine texture before generation even starts, when an image is compressed into an internal representation. This work investigates that imbalance between broad structure and fine detail. Treating the two kinds of information separately offers a route to sharper reconstructions.
Abstract
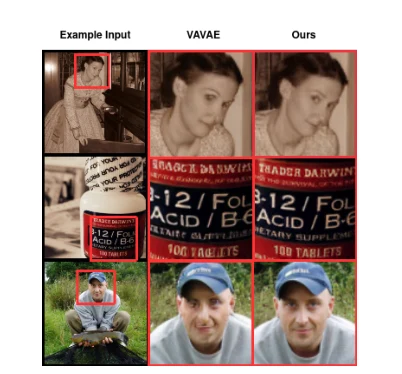
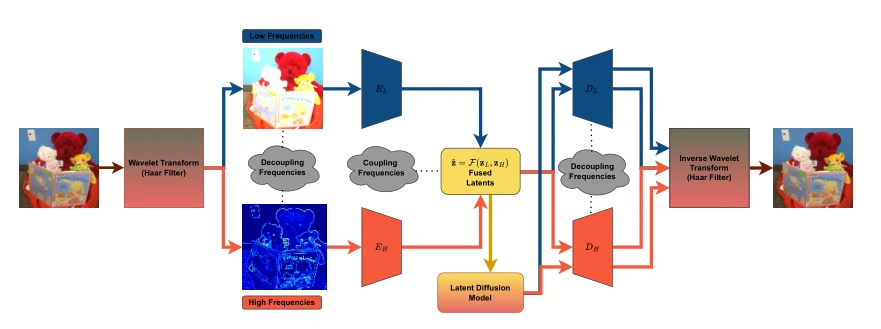
Latent generative models have shown remarkable progress in high-fidelity image synthesis, typically using a two-stage training process that involves compressing images into latent embeddings via learned tokenizers in the first stage. The quality of generation strongly depends on how expressive and well-optimized these latent embeddings are. While various methods have been proposed to learn effective latent representations, the reconstructed images often lack realism, particularly in textured regions with sharp transitions, due to loss of fine details governed by high frequencies. We conduct a detailed frequency decomposition of existing state-ofthe-art (SOTA) latent tokenizers and show that conventional objectives inherently prioritize low-frequency reconstruction, often at the expense of high-frequency fidelity. Our analysis reveals these latent tokenizers exhibit a bias toward lowfrequency information, when jointly optimized, leading to over-smoothed outputs and visual artifacts that diminish perceptual quality. To address this, we propose a wavelet-based, frequency-aware variational autoencoder (FA-VAE) framework that explicitly decouples the optimization of low- and high-frequency components. This decoupling enables improved reconstruction of fine textures while preserving global structure. Our approach bridges the fidelity gap in current latent tokenizers and emphasizes the importance of frequency-aware optimization for realistic image representation, with broader implications for applications in content creation, neural rendering, and medical imaging.
Figures
Cite this paper
@inproceedings{medi2025missingfinedetails71,
  title = {{Missing Fine Details in Images - Last Seen in High Frequencies}},
  author = {Tejaswini Medi and Hsien-Yi Wang and Arianna Rampini and Margret Keuper},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision Workshops (ICCVw 2025)},
  year = {2025},
  url = {https://arxiv.org/pdf/2509.05441?}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.