
NeurIPS 25, proceedings of the thirty-sixth Conference on Neural Information Processing Systems · 2025
MaxSup - Overcoming Representation Collapse in Label Smoothing
Why this publication matters
A common technique for reducing overconfidence can unintentionally make learned representations less informative. This paper explains that failure mode and proposes a more targeted alternative. The result is a way to moderate confidence while retaining features that remain useful for other tasks.
Abstract
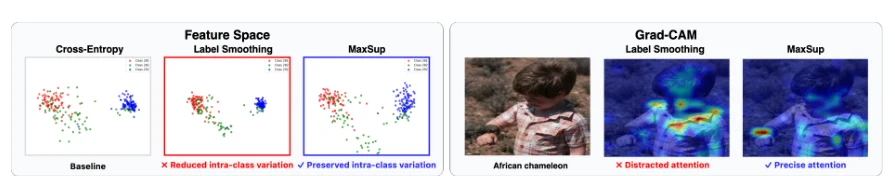
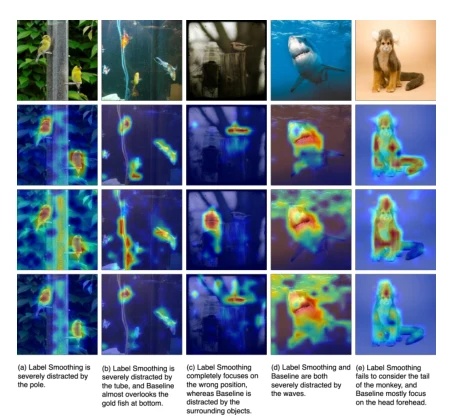
Label Smoothing (LS) is widely adopted to reduce overconfidence in neural network predictions and improve generalization. Despite these benefits, recent studies reveal two critical issues with LS. First, LS induces overconfidence in misclassified samples. Second, it compacts feature representations into overly tight clusters, diluting intra-class diversity, although the precise cause of this phenomenon remained elusive. In this paper, we analytically decompose the LS-induced loss, exposing two key terms: (i) a regularization term that dampens overconfidence only when the prediction is correct, and (ii) an error-amplification term that arises under misclassifications. This latter term compels the network to reinforce incorrect predictions with undue certainty, exacerbating representation collapse. To address these shortcomings, we propose Max Suppression (MaxSup), which applies uniform regularization to both correct and incorrect predictions by penalizing the top-1 logit rather than the ground-truth logit. Through extensive feature-space analyses, we show that MaxSup restores intra-class variation and sharpens inter-class boundaries. Experiments on large-scale image classification and multiple downstream tasks confirm that MaxSup is a more robust alternative to LS.
Figures
Cite this paper
@inproceedings{zhou2025maxsupovercomingrepresentation75,
  title = {{MaxSup - Overcoming Representation Collapse in Label Smoothing}},
  author = {Yuxuan Zhou and Heng Li and Zhi-Qi Cheng and Xudong Yan and Yifei Dong and Mario Fritz and Margret Keuper},
  booktitle = {Advances in Neural Information Processing Systems},
  year = {2025},
  url = {https://arxiv.org/pdf/2502.15798}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.