
FGVC13 workshop Efficient Fine-grained Image Retrieval with Vision Foundation Models for Industrial Objects at CVPR 2026 · 2026
Efficient Fine-grained Image Retrieval with Vision Foundation Models for Industrial Objects
Why this publication matters
Finding a replacement industrial part can mean distinguishing objects that look almost identical. This work tests that problem across viewpoints and backgrounds and explores lightweight adaptation of existing vision models. Its dataset gives researchers a concrete way to measure progress on demanding fine-grained retrieval.
Abstract
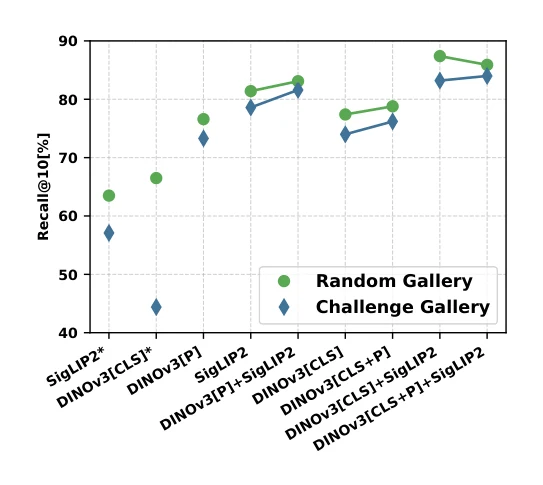
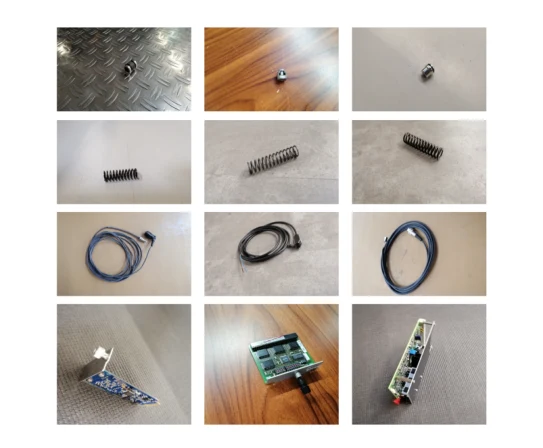
Image-based object retrieval in industrial scenarios remains highly challenging due to the combination of finegrained visual similarity between parts and significant appearance variations caused by viewpoint, background, and illumination changes. In this work, we introduce a largescale dataset for fine-grained instance-level retrieval of industrial spare parts, comprising more than 17k object instances captured under both controlled and mobile acquisition conditions. Designed to reflect realistic retrieval challenges, the dataset provides a standardized benchmark for fine-grained industrial matching. Using this benchmark, we systematically compare three recent vision foundation models—DINOv2, DINOv3, and SigLIP2—analyze how token representations affect performance, with a particular focus on the roles of CLS and patch tokens and on pooling strategies. To bridge the gap between generic pretrained representations and retrieval-specific requirements, we utilize a lightweight framework that trains on top of frozen encoders. Results across multiple evaluation settings demonstrate consistent gains over off-the-shelf embeddings and suggest that patch-token representations can play an important role in fine-grained image retrieval, especially under larger viewpoint and background variations. The dataset is publicly available at: https://github.com/imyliu1717/industrial_spare_part_dataset.
Figures
Cite this paper
@inproceedings{liu2026efficientfinegrained84,
  title = {{Efficient Fine-grained Image Retrieval with Vision Foundation Models for Industrial Objects}},
  author = {Yushi Liu and Christian Graf and Markus Spies and Margret Keuper},
  booktitle = {FGVC13 workshop Efficient Fine-grained Image Retrieval with Vision Foundation Models for Industrial Objects at CVPR 2026},
  year = {2026},
  url = {https://openaccess.thecvf.com/content/CVPR2026W/FGVC13/html/Liu_Efficient_Fine-grained_Image_Retrieval_with_Vision_Foundation_Models_for_Industrial_CVPRW_2026_paper.html}
}
Figures and abstract are reproduced from the linked research sources. Credit remains with the authors and publishers.